INFRA Signal 422
Making the MiniMax H3 Video VAE 2x Faster
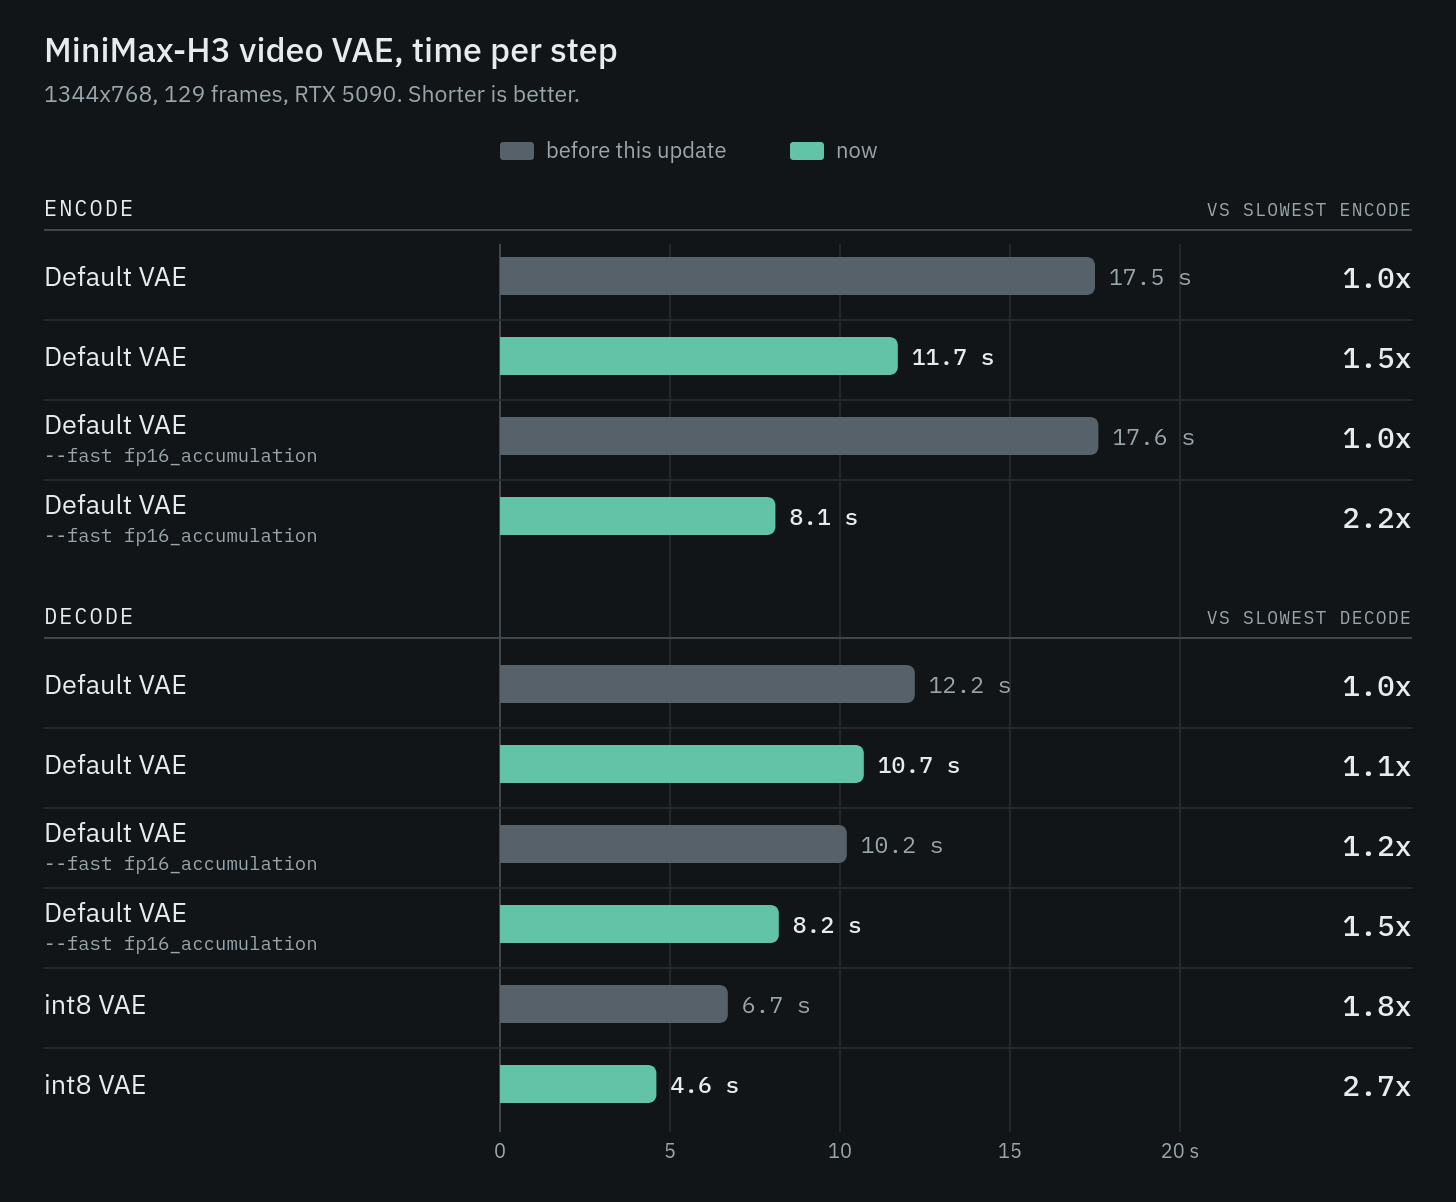 ↗
The MiniMax H3 video VAE achieves up to 2.2x faster encoding and 1.4-2.7x faster decoding on Nvidia GPUs.
Faster VAE processing reduces video workflow latency, enabling more efficient encoding and decoding pipelines for developers building video generation systems.
Written by elseif from the cluster below · every claim links back to a sourceThe three things worth knowing
Fused encoder kernel reduces memory traffic by processing convolutions in a single pass, improving encoder speed by ~1.5x.
Custom convolution with fp16_accumulation and bias folding enables 2.2x encoder speedup on supported hardware.
Int8 decoder implementation cuts decode time by 1.4x while maintaining near-lossless quality with 67.7 dB PSNR.
THE READ
What the cluster adds up to.
The fused encoder kernel eliminates intermediate memory passes during convolution operations, directly reducing GPU memory bandwidth usage and improving throughput for video encoding workloads.
Adopting the --fast fp16_accumulation flag requires no code changes but leverages NVIDIA's hardware-specific acceleration, making performance gains accessible to existing users without additional development effort.
The int8 decoder's memory-efficient design allows faster processing while maintaining quality metrics indistinguishable from standard VAE outputs, though quality remains dependent on input video characteristics.
Performance improvements are hardware-agnostic across NVIDIA GPUs but are most pronounced on consumer cards where fp16 accumulation runs at double speed, potentially widening performance gaps between hardware tiers.
Written by elseif from the cluster below · checked for specifics the sources never containedTHE CLUSTER