INFRA Signal 91
Nvidia PAIR utility joins home GPUs into a cluster for agentic AI tasks using spare cycles
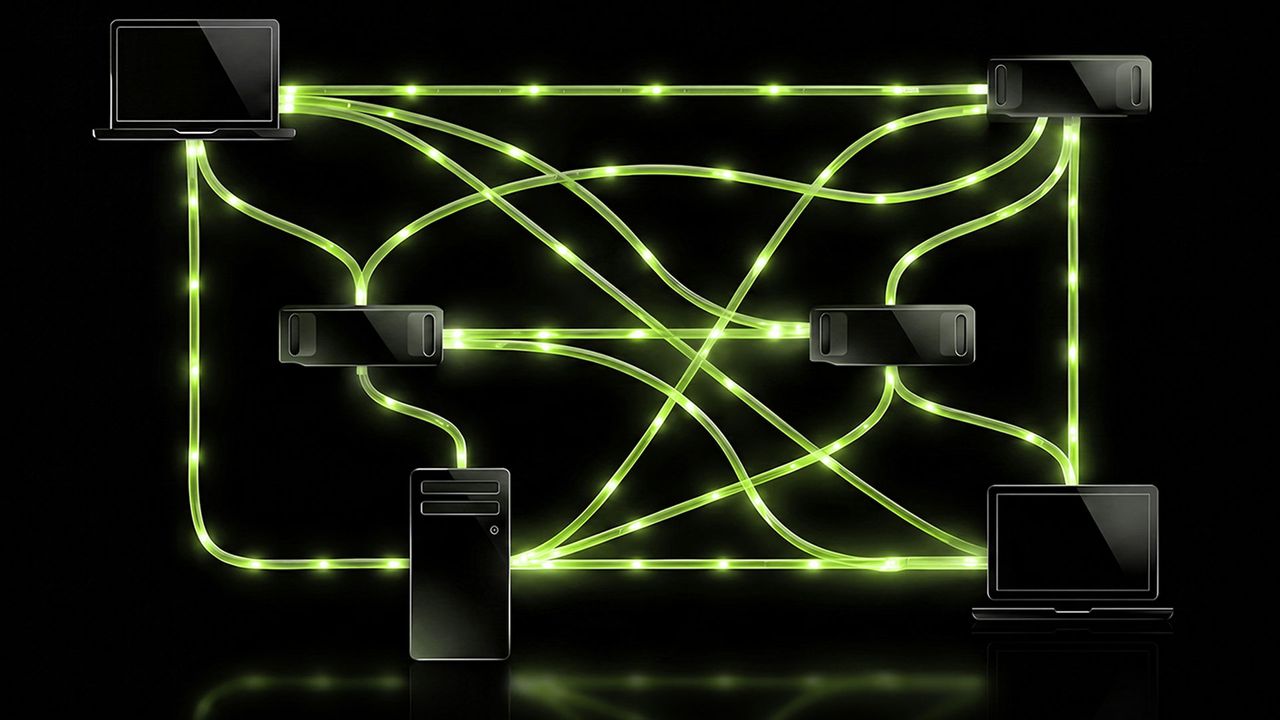 ↗
Nvidia's Personal AI Router (PAIR) enables agentic AI workloads to tap idle GPU cycles across home devices for faster, more private inference.
By distributing sub-tasks to any idle GPU on a local network, PAIR reduces contention on a single graphics card and can shorten overall job completion time. Because work stays on premises, users keep data private and avoid recurring cloud token costs while still utilizing otherwise wasted compute.
Written by elseif from the cluster below · every claim links back to a sourceThe three things worth knowing
PAIR acts as a proxy for AI front-ends such as LM Studio or Ollama, dispatching agentic sub-tasks to other home systems that report spare GPU capacity.
The orchestrator is elastic; it does not reserve fixed resources and reallocates work as GPUs become busy or free again.
Participating nodes must run Ollama or LM Studio and have PAIR installed, and the utility supports Windows, macOS, Linux, RTX 20-series or newer GPUs, DGX Spark/GB10 boxes, and Macs with M4-series or later processors.
THE READ
What the cluster adds up to.
Nvidia introduced a utility called Personal AI Router (PAIR) that treats every GPU in a household as part of a single compute cluster. The tool intercepts agentic AI workloads from a primary PC and splits them into sub-tasks. Those sub-tasks are sent to other machines on the same local network that report idle GPU cycles. Results are gathered back to the originating application, effectively turning spare home graphics cards into a distributed inference fabric.
To use PAIR, each participating system must run the PAIR client and have an AI front-end such as Ollama or LM Studio installed. Discovery of nodes relies on mDNS with an IP address fallback, so no manual configuration is required. The orchestrator does not reserve fixed GPU slices; it continuously measures available cycles and assigns work elastically. This means the system can scale up or down as family members start or stop gaming, creative work, or other AI jobs.
Because GPU availability fluctuates, PAIR cannot guarantee a specific quality of service; tasks may slow down if many nodes become busy simultaneously. The utility is best suited for long-running, non-time-critical agentic workloads where opportunistic use of spare cycles yields a net benefit. If a node is actively rendering a game or performing its own AI inference, PAIR will simply avoid assigning new work to that GPU until it frees up. Heterogeneous models across nodes are allowed, but a sub-task requiring a particular model can only run on machines that have that model loaded.
Only one feed, Tom's Hardware, carried the announcement, so there is no independent corroboration of the claimed performance gains or ease of setup. The description relies on Nvidia's own statements about PAIR's behavior and requirements. Engineers should treat the reported capabilities as preliminary until further testing or additional sources confirm the utility's real-world effectiveness.
Written by elseif from the cluster below · checked for specifics the sources never containedTHE CLUSTER