WEB Signal 56
Four-axis Bayesian model capability index now includes human performance baseline
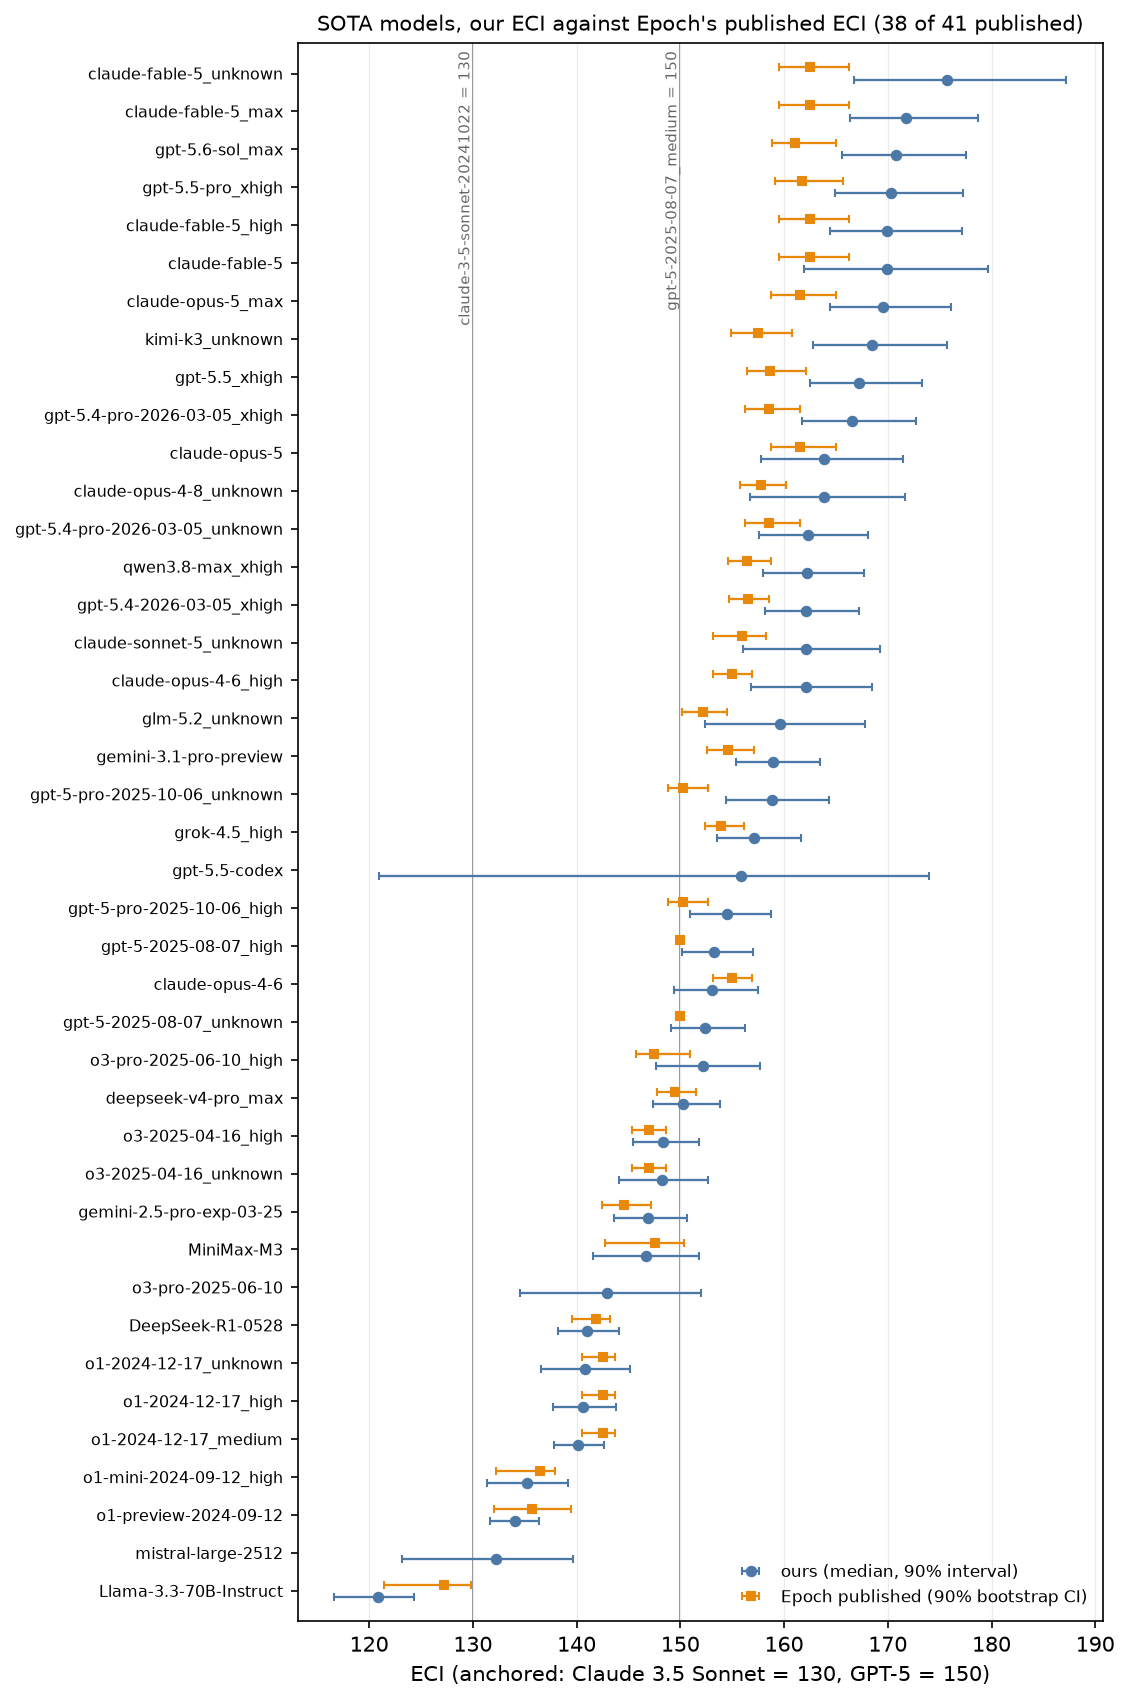 ↗
The General-Purpose AI Policy Lab released an index that compresses multiple benchmark scores into a single Bayesian metric per model and adds human baselines for comparison.
A unified metric lets engineers compare diverse models without juggling many separate benchmarks. Adding human baselines provides a concrete reference point for assessing how far AI systems have progressed relative to people. Policymakers and developers can use the index to prioritize research directions and allocate resources more effectively.
Written by elseif from the cluster below · every claim links back to a sourceThe three things worth knowing
The index aggregates many benchmark scores into one Bayesian score for each model.
It follows the framework described in the Rosetta Stone paper.
Human baseline scores are mapped onto the same scale to enable direct model-human comparison.
THE CLUSTER